tags: cofacts, meeting note GA: UA-98468513-3 —
20231011 會議記錄
:::info
- 所有會議記錄
- 線上出席:T, cai
- Workis 出席:bil, nonumpa, mrorz
- https://gather.town/app/z3x18KQFgZCX8MeZ/cofacts :::
:potable_water: Release pipeline
:star: Released to production
:electric_plug: API
- Write AI transcript https://github.com/cofacts/rumors-api/releases/tag/release%2F20231005
:globe_with_meridians: Site
- License and auto deploy https://github.com/cofacts/rumors-site/releases/tag/release%2F20231005
:robot_face: rumors-line-bot
- Staging auto deploy https://github.com/cofacts/rumors-line-bot/releases/tag/release%2F20231005
:rocket: Staging
:electric_plug: API
Adding non-null to Article and Reply and ArticleReply https://github.com/cofacts/rumors-api/pull/320
Only include high confidence paragraphs in OCR https://github.com/cofacts/rumors-api/pull/321
:robot_face: rumors-line-bot
Rewrite webhook handlers with Typescript
- https://github.com/cofacts/rumors-line-bot/pull/366
- https://github.com/cofacts/rumors-line-bot/pull/365
Testing checklist
https://lin.ee/1QUzEX4nI
- 應可送出「全新訊息」
- 問訊息來源時選擇「我自己打的」會被擋下。
- 選擇「整篇轉傳」後會詢問是否要送出訊息。
- 不同意送出訊息後可以收到感謝。
- 同意送出訊息後就會送出訊息,並得到:
- Cofacts article page 按鈕
- 寫理由的按鈕
- (若沒開啟推播)應該要看到「開啟小鈴鐺」泡泡,且可打開 setting 頁面
- 「分享到 Facebook」、「分享到 LINE」且可以正常運作
- 可從聊天視窗內打開理由視窗,繼續填寫理由送出。查看 article page 看理由是否有被送出。
- 可以再打開理由視窗,此時會載入上次填寫的理由。修改理由送出後,查看 article page 看理由是否有被送出。
- 送出「沒回應」的舊訊息,應可送出新理由
- 文章的「N 人回報」應該仍然要 + 1(除非測試者已經針對該篇送過 reply request)。
- 可從聊天視窗內打開理由視窗,繼續填寫理由送出。查看 article page 看理由是否有被送出。
- 可以修改理由送出。查看 article page 看理由是否有被送出。
- (若沒開啟推播)應該要看到「開啟小鈴鐺」泡泡,且可打開 setting 頁面
- 送出「有回應」的舊訊息,應自動回傳回應
- 應列出訊息所有的回應
- 選擇回應之後可以幫回應 upvote
- 可以再次選擇 downvote
- 選完回應之後,還可以捲回去選其他回應
- (若沒開啟推播)應該要看到「開啟小鈴鐺」泡泡,且可打開 setting 頁面
- 送各種圖片訊息進資料庫,可以正確 OCR
⛔️ Release Blockers
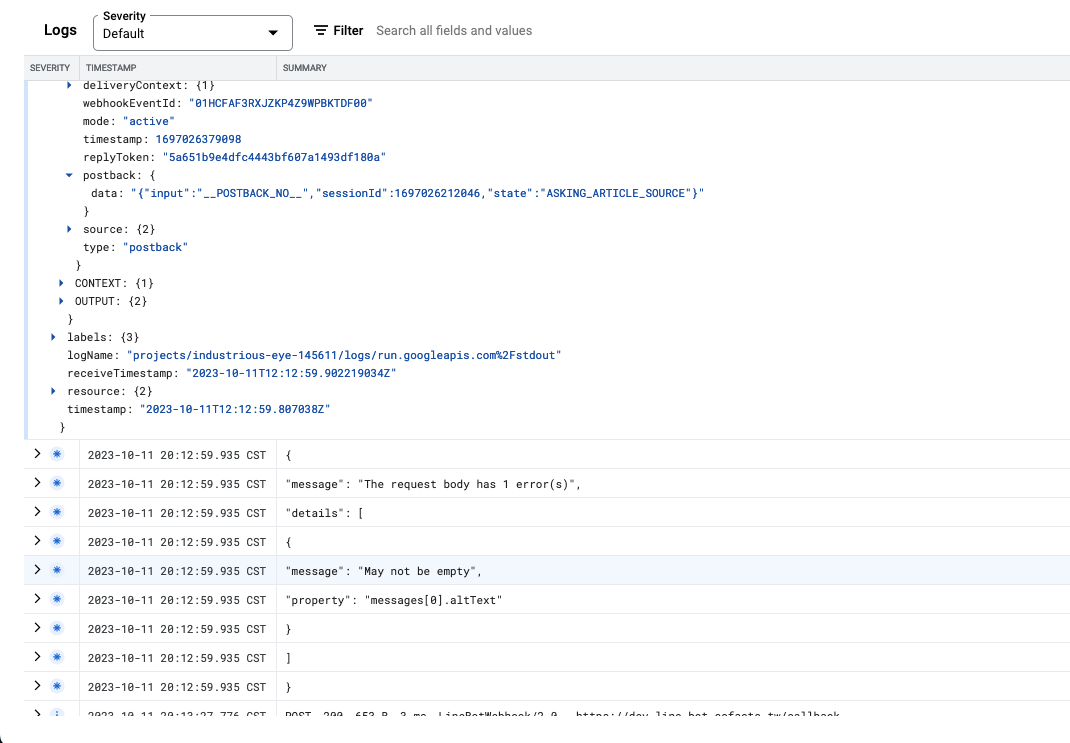
altTextcannot be null
未竟項目
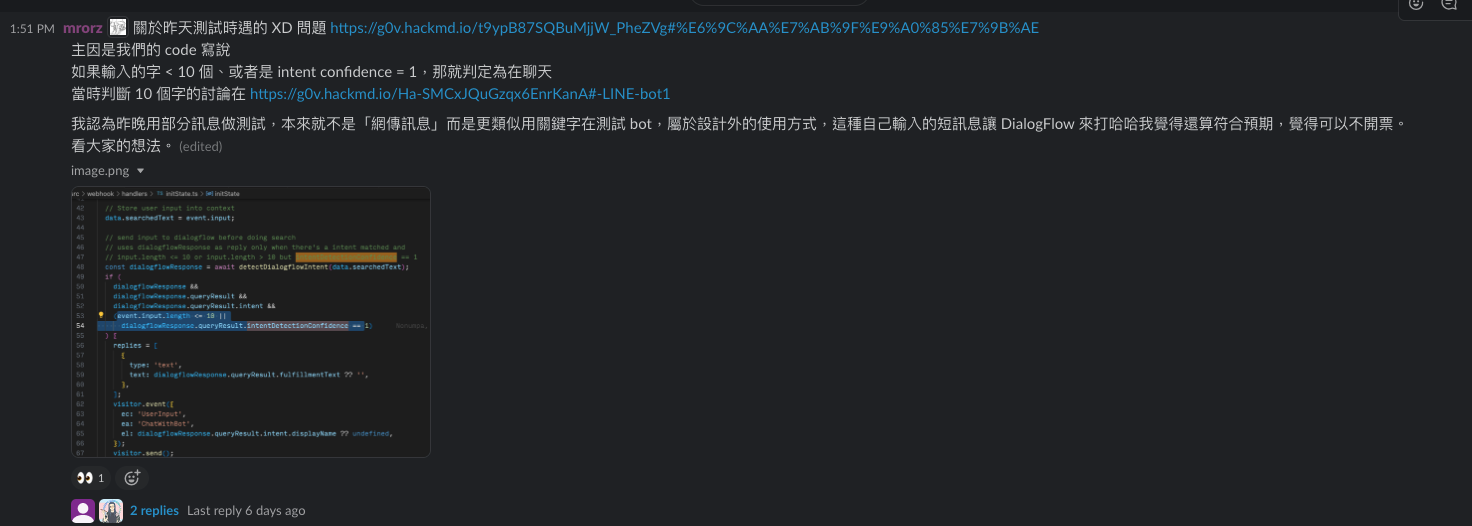
發現 chatbot 會亂回 XD
confidence threshold 應為 1,好像壞了
{
  "responseId": "900b37b1-cf3f-4511-9c8a-3b4e33241e39-ce1e108a",
  "queryResult": {
    "queryText": "以色列武器來自烏克蘭",
    "parameters": {},
    "allRequiredParamsPresent": true,
    "fulfillmentText": "XD",
    "fulfillmentMessages": [
      {
        "text": {
          "text": [
            "XD"
          ]
        }
      }
    ],
    "intent": {
      "displayName": "Happy"
    },
    "intentDetectionConfidence": 0.5234231,
    "languageCode": "zh-tw",
    "sentimentAnalysisResult": {
      "queryTextSentiment": {
        "score": 0.1,
        "magnitude": 0.1
      }
    }
  }
}
:::info
開票處理
Update:
Not an issue, 規格外的使用
:::
CCPRIP
[Comm] crowd-sourced transcript
https://g0v.hackmd.io/@cofacts/rd/%2FOhGIQzoxR5eF6audQuS_FQ [name=nonumpa]
- writing tests [name=nonumpa]
我注意到 AI transcript 出來的文字 會有刪除一字之後 paragraph 就會爛掉的現象 我的直覺是 原本 AI 出來的文字單純以
\n斷行 但 ProseMirror 要求以<p><br>斷行 所以就會直接爛掉 老實講,我會希望 ProseMirror 可以是一個單純的文字編輯器更好 之後我頂多只會加上特殊符號的 syntax highlight 而已(例如約定#開頭的行爲註解,方便標記分區或 timestamp)之類 [name=mrorz]
- 跟 4000 / cai 說的,斷行按了兩三個、只要判斷成一個就好 [name=nonumpa]
- 我覺得編輯模式符合原本的也 OK [name=mrorz]
- 但這樣輸入框會變長 [name=nonumpa]
- 應該不會有人亂斷行。有 AI 作為基底的話,大家應該會去編輯 AI 內容。因此編輯模式是純文字編輯器應該還行 [name=mrorz]
:::info 開票於 rumors-site, good-first-issue (prosemirror settings) :::
[Comm] AI transcript
Migration
https://g0v.hackmd.io/wkx286lmTDaFUpgRhnUawQ?both#Migration-of-exisitng-media-articles
- Handle images first
- Paused due to accuracy issue
Revisiting OCR accuracy
OCR的偵測敏感度(?)可以調比較低嗎 [name=cai]
- Research: https://g0v.hackmd.io/wkx286lmTDaFUpgRhnUawQ#Google-vision-API
- PR: https://github.com/cofacts/rumors-api/pull/321
:::info confidence 降低到 0.75 好像也 OK :::
Whisper hallucination
AI 逐字稿影片類的似乎比較適合在保健秘訣那種旁白等於謠言內容的影片。 碰到配樂跟影片內容無關的反而增加麻煩。 [name=cai]
Whisper 在無聲區域也常常跳出廣告文字,因為來源訓練資料的問題 [name=kiang]
關於 Whisper 無聲區的 hallucination 之前查到的是用另一個模型去做 voice activity detection (VAD) 然後只取有 voice activity 的 transcript https://g0v.hackmd.io/wkx286lmTDaFUpgRhnUawQ#Whisper
https://cofacts.tw/article/TvR6AosBAjOeMOklfe-g 原來 train data 是來自群眾協作字幕的社群呀
無聲 https://cofacts.tw/article/JvRhAosBAjOeMOklpe-v
我會希望他不要翻譯耶其實 雖然他翻得還 OK https://cofacts.tw/article/FPRXAosBAjOeMOklXO9y
前面好好的 後面沒聲音開始起肖 https://cofacts.tw/article/m_S3AosBAjOeMOkls-_a
慘叫 https://cofacts.tw/article/jvSIBYsBAjOeMOklDvOv
無法解釋 明明有這麼明顯的口白 https://cofacts.tw/article/MvTSCosBAjOeMOklBvlJ Whisper desktop 沒問題。會不會是網路速度、影片沒傳完? [name=cai]
- 覺得滿好用,不用看影片就大致知道在講什麼非常愉快 [name=bil]
TODO
- See if we can reproduce the hallucination
- See if confidence of hallucination part is low; if so, we can apply threshold
- See if changing prompt can work
Google cloud speech-to-text
google cloud speech to text 有出 v2 而且有做 VAD 的樣子 https://cloud.google.com/speech-to-text/v2/docs/voice-activity-events [name=johnson]
https://g0v.hackmd.io/wkx286lmTDaFUpgRhnUawQ#V2-API
:::info 開成票讓大松的人做實驗?
- 抗 hallucination 成效
- 不同語言的問題
- 處理時間(等多久?) :::
[Comm] Article group / cooccurrence implementation
- Move context data to postback action –> Need to type context & postback first –> Need to type handlers first (we are here)
- Will convert context type & postback type into unions
- Use Arktype to define type & assert type contains required fields in each handler
- rumors-db 的 zod 拔不掉,因為同時會把 zod object 轉 big query schema
- arktype 還在 alpha
:::success 先用 zod 比較保險 :::
Cofacts data
- https://github.com/cofacts/opendata/pull/27
- Includes anonymized users
- 如果 article 裡面有名字的話有風險 [name=bil]
- 但 article 更早以前就出去了 [name=mrorz]
- https://huggingface.co/datasets/Cofacts/line-msg-fact-check-tw/discussions/2/files
Chatbot downtime
- MongoDB free DB (512MB) 滿了 –> USD 9/mo 的付費版本 (2GB)
- Disk full notification
- https://hackmd.io/i0GcWSSVQNeDQ_OBebyk6Q?both
大松籌備
報名
2023/10/15
- https://github.com/cofacts/rumors-site/issues
- https://github.com/cofacts/rumors-line-bot/issues
TODO:
- prosemirror settings
- Google cloud speech to text 實驗
- Convert ground truth to data ready to train AutoML
- Good first issue
MozTW 服務學習
https://docs.google.com/presentation/d/1ZnbJy5_qpjOYPtkoH88v3X8IGVQ6yNVEloRipg_MVzc/edit#slide=id.g24b05e238b0_0_0